Article #12
Published: 30 September 2026
By Stan van Gemert | S10 Group
By Stan van Gemert
The CISO series
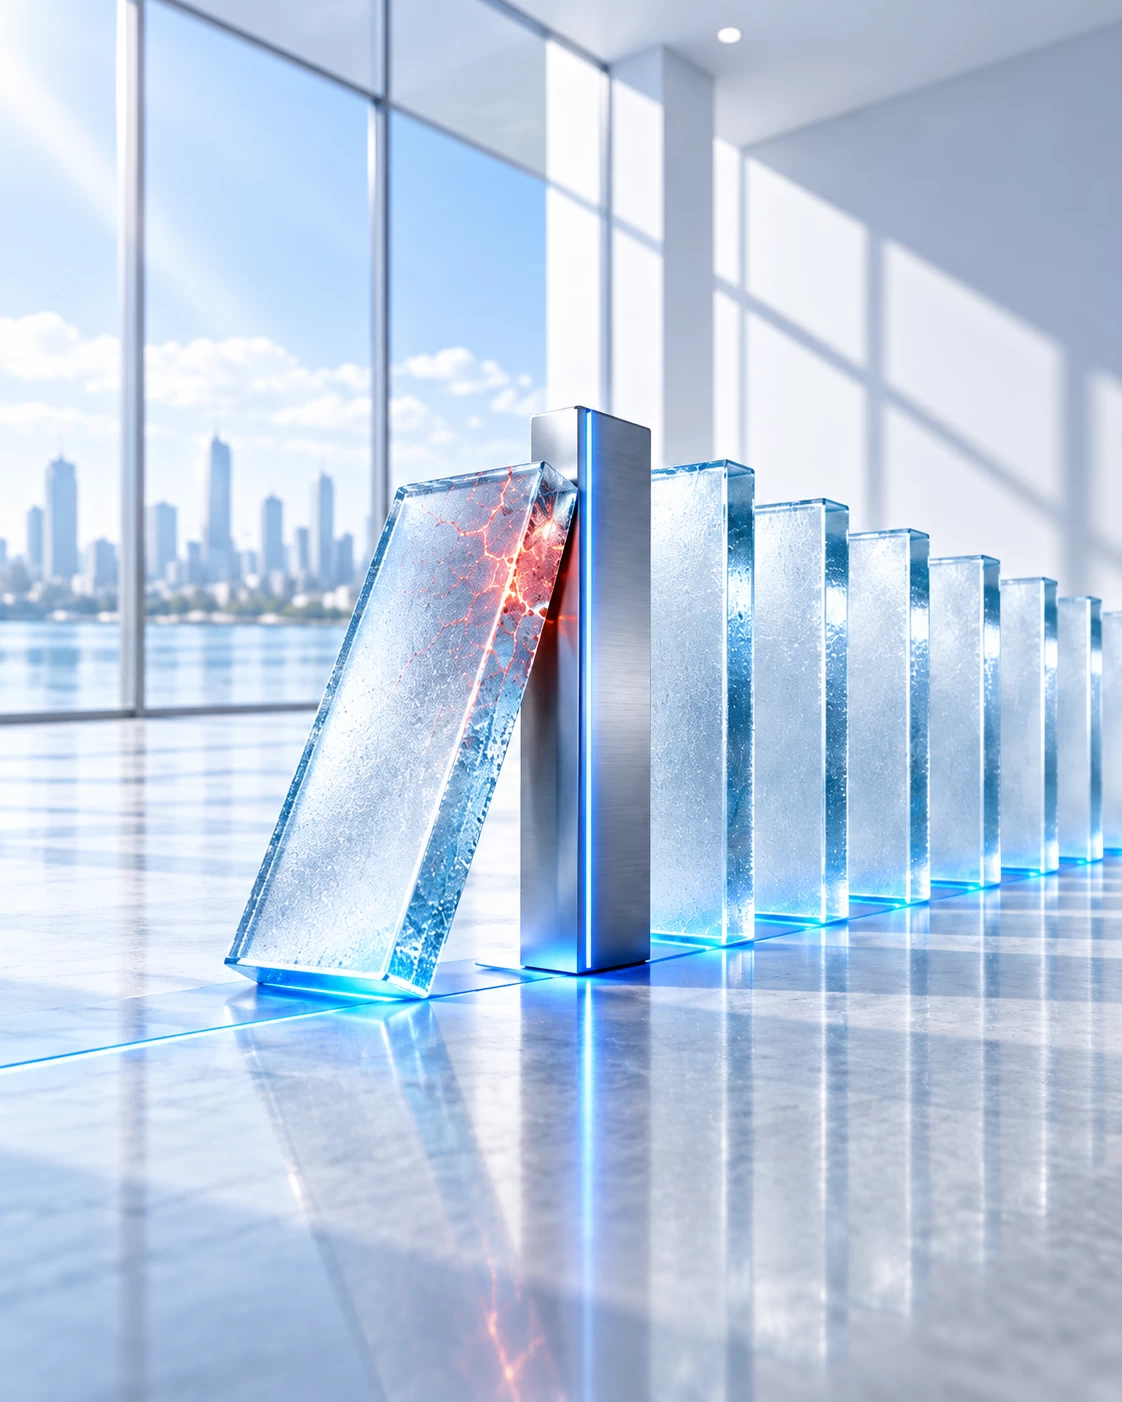
The data platform was online, the login portal responded and the finance workflow still moved. The first dashboard was green enough to calm the room until someone asked which activity could still be relied upon.
That question changed the incident. A valid login might represent a stolen credential, a routine query might be active extraction and an instruction from a familiar executive might be synthetic. An administrative change could have been made through permissions that were legitimate yesterday and dangerous now. Availability remained visible, but the evidence behind safe operation was becoming unreliable.
Many cyber incidents become harder at precisely that point. Nothing has failed clearly enough to force a common response, yet your teams can no longer assume that a working system, recognised identity or completed workflow is evidence of legitimate activity.
Identity-based attacks are difficult to recognise because the first evidence may look like normal work. Logs can record a known user while the person behind the session is an attacker. A cloud console can show an administrator even though the credential has been stolen. A service account may act within its permissions while violating the purpose for which those permissions were granted.
The response should not treat every unusual action as hostile; that would make normal operations impossible. It should recognise that authentication is only one part of the decision. Behaviour, timing, destination, device, privilege and consequence determine whether continued access remains proportionate.
Once those signals become inconsistent, your teams are managing two linked problems: the suspicious activity itself and the declining reliability of the evidence used to decide what should continue.
The board will ask whether customers are affected, legal and privacy teams will ask whether notification duties have been triggered, and operations will need to know which services can remain available. Communications will need language that can survive the next confirmed fact. The CISO may not yet be able to provide one definitive account because scope depends on signals that are still being tested.
If valid accounts may be compromised, user activity is uncertain. If query logs contain attacker activity, the exposure picture is uncertain. If privileged changes may have been made by an adversary, recovery state is uncertain. Waiting for every ambiguity to disappear gives the incident more time; acting without a bounded rationale can create unnecessary disruption.
Your response model therefore needs explicit confidence levels, reversible actions and pre-agreed authority. Teams should know what is confirmed, what remains plausible, which evidence threshold permits a containment move and who can accept the operational consequence while investigation continues.
If the systems remain available but the evidence is unreliable, which activities can your teams pause before certainty returns, and who has authority to make that decision?
Containment does not restore reliable evidence by itself. It limits what uncertain access and harmful behaviour can still do while investigators rebuild the picture. A suspect session can be terminated, an affected workload separated, a data-movement route restricted or a privileged path narrowed before every identity question has been resolved.
The distinction matters because uncertainty expands through action. Every unchecked query, export, session and administrative change can increase the number of systems, people and decisions that later require validation. A bounded intervention reduces that expansion without treating the entire environment as hostile.
Detection tells your teams that something may be wrong. Containment gives them a way to reduce the consequence while they establish what is true.
A service that answers is not automatically ready for unrestricted use. Where identity or administrative state has become uncertain, reconnection may require token and credential rotation, privileged-account review, query analysis, renewed access boundaries and validation that recovery has not reopened the same path.
The objective is not perfect certainty about every event. It is enough reliable evidence to explain which identities, routes, workloads and transactions may operate again, under which conditions and with which monitoring. Recovery becomes defensible when those decisions are explicit rather than inferred from uptime.
Your CISO cannot rebuild operational confidence alone, but the role includes helping the executive team distinguish availability from safety, fact from assumption and reversible action from irreversible exposure. That work connects technical evidence to decisions about access, continuity, communication and recovery.
The boundaries should exist before the incident: which identities and systems carry exceptional authority, which requests require independent verification, which behaviours justify immediate interruption and which evidence must be preserved so that each decision remains traceable afterwards.
Reliable operation is therefore not a background assumption. It is a condition your teams must be able to test, narrow and restore.
A ransom note, failed portal or production outage gives an incident a visible name. The earlier failure is often quieter: a session that should have been challenged, a query whose purpose changed, an instruction that imitated authority or an administrative action that passed the technical check while violating the business reality.
By the time systems fail, the evidence behind safe operation may already have been weakening for days. Availability is therefore a poor final reassurance. The stronger question is whether your teams still know what they can safely allow, interrupt and restore.
Your organisation remains governable when it notices the loss of reliable signals early and limits what uncertainty can still do before visible failure removes the remaining choices.
Our platform adds an operational containment layer after prevention has been bypassed. It does not replace identity governance, forensic investigation, independent request verification or the business owners who decide which activities may continue. Our role is to help authorised teams interrupt harmful behaviour while those disciplines establish what happened and what remains safe.
Ransomware Containment is our core platform. Its agentless monitoring identifies active file-encryption behaviour across SMB and NFS activity and can isolate the affected user or session while existing antivirus and endpoint controls remain active. Server Intrusion Protection and Virtual Server Protection are additional features running on the same platform, extending control to compromised administrator use on servers and host-level threats in virtual environments.
Our platform helps interrupt lateral movement and data-theft paths while investigation continues and recovery decisions are being made. The practical value is clear: keep the incident boundary smaller, preserve room for evidence-led decisions and prevent a minor compromise from becoming an operational cascade.
The next publication turns from degraded operating evidence to the period in which the imbalance was created. "The Attacker Had a Map Before Leadership Had a Picture" examines how reconnaissance gives an attacker a practical view of accounts, dependencies and recovery paths before your executive team sees the full incident.
It asks what must already be containable when the first meeting begins with fragments rather than a map.