High-key conceptual visual of a glass cube preserving a stable blue control core while chaotic red threat energy is neutralised at the outer boundary.High-key conceptual visual of a glass cube preserving a stable blue control core while chaotic red threat energy is neutralised at the outer boundary.

Control Under Pressure

The operating doctrine for staying governable
when prevention has already failed

Control Under Pressure

The operating doctrine for staying governable when prevention has failed.

The first sign of lost control is often not an outage. Systems may still be running, dashboards may still be updating and the SOC may already be alerting. Yet the people responsible for the response may still be unable to decide which access, service or connection can safely remain in use.

Is the login legitimate? Is the recovery point clean? Can a supplier route remain open? Has sensitive data already left? Who may isolate a region or revoke access before the full incident picture is known?

Cyber resilience becomes operational at that moment. Your organisation must still authorise action, enforce boundaries, preserve evidence and keep essential work moving without the comfort of complete certainty.

Control Under Pressure is our doctrine for that interval. It does not promise that every incident can be prevented or reduced to faster detection. It describes how your organisation preserves the ability to change the course of an incident while the facts continue to develop.
CONTROL UNDER PRESSURE BEGINS WHEN CERTAINTY ENDS
The question is not whether the organisation can see the incident.
The question is whether it can still shape the outcome.

Why visibility is not enough

Most security environments can generate information about a developing incident. Alerts, telemetry and threat intelligence help your teams understand what may be happening, but information does not interrupt an unsafe session, restrict a compromised account or stop encryption from reaching another system.

The gap becomes visible when a credible signal exists but the authorised response is still unclear, too broad or too slow. Your organisation then has awareness without a proportionate move that can change the incident path.

Control Under Pressure connects evidence to action. It requires named authority, pre-agreed boundaries and containment measures that can be executed while investigation and operational decisions continue.

Visibility explains the incident. Executable control changes what the incident can reach next.

Visibility describes reality.
Control changes reality.

The five dimensions of control under pressure

A cyber incident becomes difficult to govern when several capabilities weaken at the same time. The questions below separate those capabilities so that each one can be prepared, assigned and tested.

The five dimensions of control under pressure

A cyber incident becomes difficult to govern when several capabilities weaken at the same time. The questions below separate those capabilities so that each one can be prepared, assigned and tested.

Verification control

Which identities, systems, suppliers, recovery points and access paths have enough evidence behind them to remain in use?

Containment control

Which account, session, workload or connection must be restricted before the incident expands?

Recovery control

What can be restored or reconnected safely, and in what sequence?

Data control

What information has left, what movement is continuing and what exposure can still be prevented?

Decision control

Who may act before certainty exists, what evidence is required and how will the decision be recorded?

These five dimensions describe one operating model, but they should not collapse into one repeated idea. Verification establishes what may remain in use. Containment limits movement. Recovery governs return. Data control limits irreversible exposure. Decision control makes action authorised and defensible.

Verification control

Verification control asks which identities, systems and access paths have enough evidence behind them to remain in use.

A system can be online while the account operating it is compromised. A token can still validate after it has been stolen. A supplier connection can remain technically available after its credentials or route have become suspect. Backups can exist without providing a safe recovery point.

Your response therefore needs explicit verification gates. Which privileged sessions have been revoked? Which identities have been re-established? Which supplier routes have been reviewed? Which recovery point has been checked against the known incident timeline?

The objective is not immediate certainty across the whole environment. It is enough evidence to decide what can remain available, what must be restricted and what may return next.

Working access is not proof of legitimate access.
Verification prevents recovery from reopening the path the attacker used.

Containment control

Containment control asks a different question: "what must be stopped from moving?"

This is where many organisations discover the gap between detection and control. The SOC may see something credible. The tooling may generate a high-confidence signal. The security team may recognise lateral movement, suspicious authentication, data staging or abnormal command behaviour. But unless the organisation can interrupt that behaviour, the signal remains information.

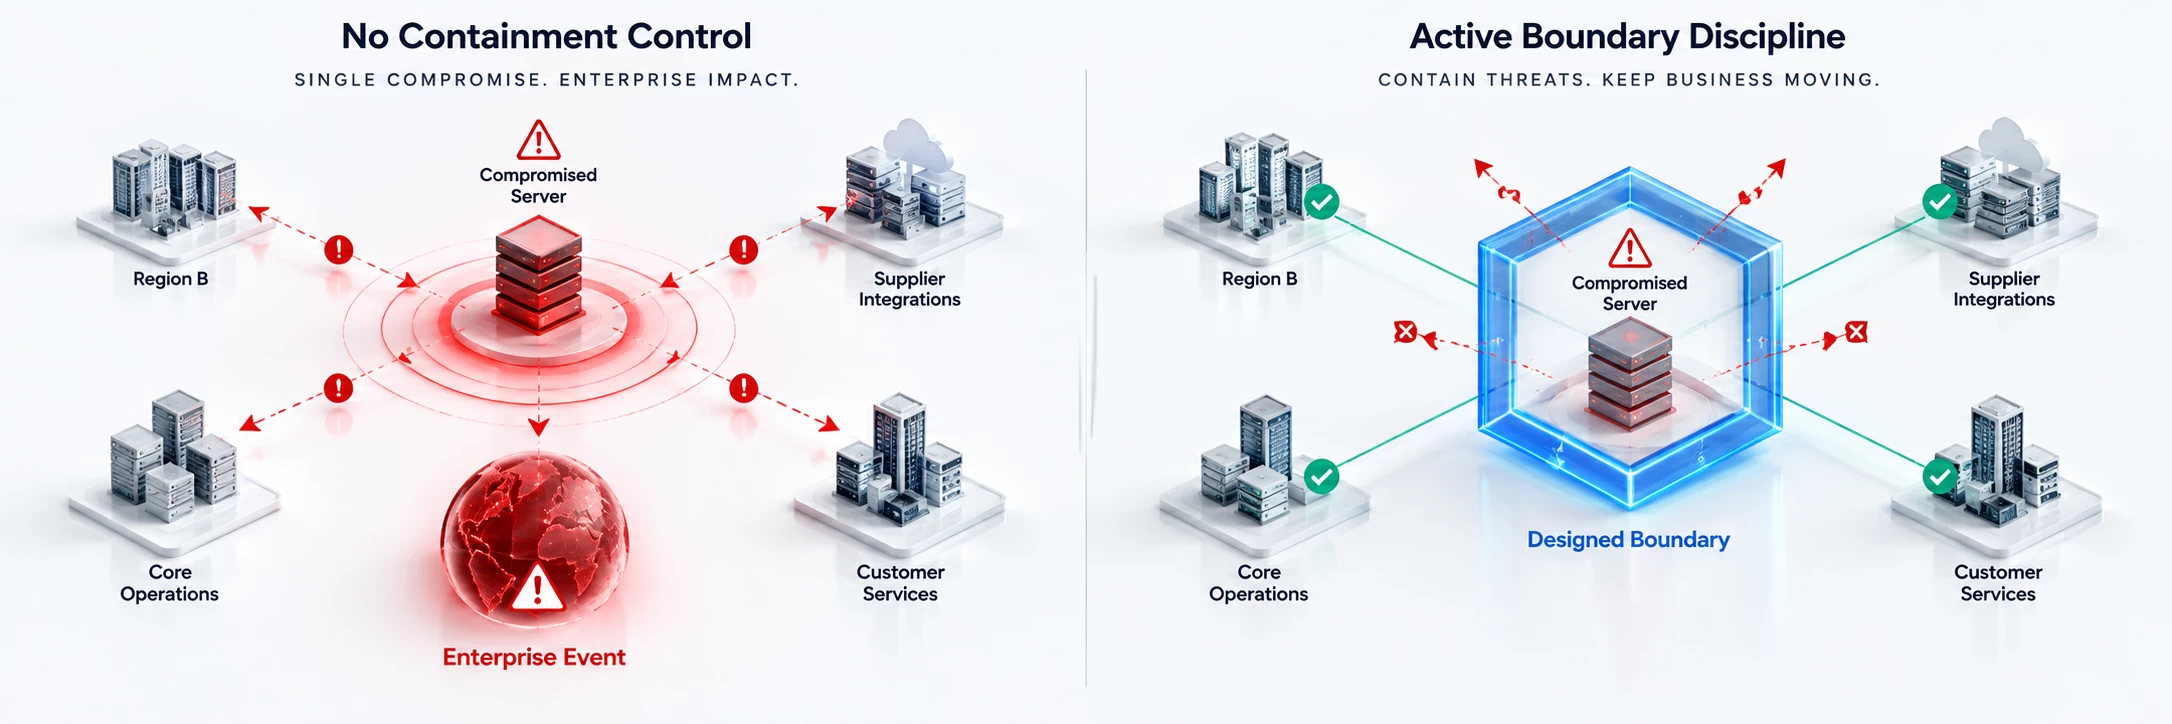
Containment is not panic. It is not pulling every plug. It is not indiscriminate shutdown. Containment is boundary discipline: deciding what must be isolated, restricted, segmented, throttled, revoked or stopped so that one compromised path cannot become an enterprise event.

That decision has business consequences. Shutting down a region, isolating a server group, suspending a supplier integration or revoking privileged access may interrupt operations. But delay also has consequences. It gives the attacker time to expand the blast radius.

Control under pressure requires those boundaries to be designed before the crisis demands them.

Infographic comparing no containment control with active boundary discipline, showing a compromised server spreading across the enterprise on the left and being isolated within a designed boundary on the right while core operations, customer services, supplier integrations and Region B remain protected.

Recovery control

Recovery control asks what can return safely and in what sequence.

A restored backup, restarted service or green dashboard does not by itself establish that attacker persistence, compromised privilege or an unsafe supplier route has been removed. Reconnection needs evidence that relates to the incident that actually occurred.

Your teams need verification gates for identities, recovery points, network paths and critical dependencies. Each gate should state what evidence is required, who accepts the remaining risk and which services may operate in a controlled degraded mode while further checks continue.

Speed still matters, but an unverified return can rebuild attacker access into the recovered environment. Recovery control replaces a single restore moment with a governed sequence of evidence, authority and reconnection.

Data control

Data control asks: "what has left, and what can still be stopped from leaving?"

This question changes the incident.

If data has already been copied, the organisation is no longer managing only infrastructure disruption. It is managing information that may now exist outside its boundary. Containment can remove attacker access, but it cannot automatically remove leverage over data that has already left.

Control under pressure means the organisation must distinguish between technical control and information control. A server can be rebuilt. A credential can be revoked. A segment can be isolated. But copied data cannot be made un-copied by restoring systems.

This is where containment timing matters. Preventing, interrupting or limiting unauthorised data movement can change the entire consequence profile of the incident.

A ransomware incident without data loss is already serious. A ransomware incident with data theft becomes a legal, regulatory, customer, reputational and human consequence event.

Decision control

Decision control asks who may act before the full incident picture is known.

During a live incident, the most valuable containment decision often arrives before complete technical certainty. The executive team may need to accept service disruption. An authorised responder may need to revoke access, isolate a workload or restrict a supplier route. Legal and communications teams may need to prepare an account that separates verified facts from open questions.

Those decisions should not depend on an improvised committee. Your organisation needs named authority, evidence thresholds, escalation routes and a decision record that explains what was known and why the action was proportionate at that moment.

The board sets expectations and risk appetite. Executives accept material operational trade-offs. Authorised incident teams need room to execute the containment actions already assigned to them.

A plan becomes useful only when authority can move at incident speed.

Why containment gives the executive team room to act

Containment reduces the number of variables changing while decisions are being made. Restricting a compromised account, session, server or connection can narrow the affected field, preserve evidence and prevent one technical problem from becoming a wider operational event.

That narrower field gives the executive and incident teams more useful options. They can decide which services must continue, which may remain degraded and which recovery steps have enough evidence behind them to proceed. Legal and communications teams can also work from a more stable account of what was restricted and what remains under investigation.

Containment does not create perfect certainty or remove every consequence. It prevents continued expansion from setting the agenda faster than your organisation can decide. That is why it is central to Control Under Pressure.

Why recovery without trust is unsafe

Recovery is where pressure becomes most dangerous. The business wants systems back. Customers want service. Executives want a timeline. Regulators want facts. Employees want clarity. Every hour of disruption has a cost. That pressure is understandable. It is also exactly why recovery must be governed.

A fast rebuild on an untrusted foundation can return the attacker to the business faster than the business returns to itself. A restored backup can reintroduce contaminated assumptions. A re-enabled identity path can reopen the door. A supplier connection can reconnect the original route. A public statement can overpromise before the evidence supports it.

Control Under Pressure therefore treats recovery as a confidence problem, not only a restoration problem. The question is not: can this be switched back on? The question is: what proves it is safe enough to reconnect?

Where our platform fits

Our platform becomes relevant when credible evidence requires an immediate containment move. It complements your existing prevention, EDR, monitoring, identity and recovery controls by giving authorised teams a way to interrupt active ransomware encryption and restrict harmful behaviour before more systems or services are affected.

Ransomware Containment is the platform. Server Intrusion Protection and Virtual Server Protection are additional features that extend protection to compromised administrative access and supported virtual infrastructure.

Our platform does not replace the wider operating doctrine described on this page. Your organisation still needs decision authority, recovery gates, evidence preservation and communications discipline.

The executive question

Control Under Pressure sets a demanding but practical standard: when something goes wrong, can your organisation still authorise and execute actions that change the incident path?

That standard depends on more than detection. Credible signals must lead to bounded action. Recovery must follow evidence. Further data movement must be interruptible. Decision rights must remain clear while the facts develop.

The executive question is therefore direct: when pressure arrives, does control remain executable?

Control under pressure is the ability to act proportionately after prevention has failed
and before the incident has finished expanding.

A controlled ransomware comparison

Our remote ransomware resilience assessment has a deliberately narrow purpose. In your own isolated test environment, it compares agreed file-encryption scenarios with your existing security controls active, first without our Ransomware Containment platform and then with it enabled.

The observable question is whether active encryption is contained sooner and whether the reachable test scope becomes smaller. The assessment does not validate decision authority, identity integrity, data-exfiltration control, Server Intrusion Protection, Virtual Server Protection, recovery readiness, governance or business continuity. But, during the assessment session, we can walk your team through the wider containment layer.

Alongside the assessment results, we can explain how our platform and its additional Server Intrusion Protection and Virtual Server Protection features, helps detect and interrupt lateral movement, reduce the risk of data theft, protect remote server access and defend virtual environments such as VMware and Hyper-V. That makes the session useful not only as a ransomware-containment test, but also as a practical discussion about what your organisation can still control when identity, privilege and infrastructure trust come under pressure.

Further readings