Article #20
Published: 16 October 2026
By Stan van Gemert | S10 Group
By Stan van Gemert
When attacks move series
The previous publication, "The Goal Is Not Perfect Prevention", asked which essential service your organisation can sustain safely after normal operation is disrupted. That operating choice depends on the foundations beneath the service and its fallback.
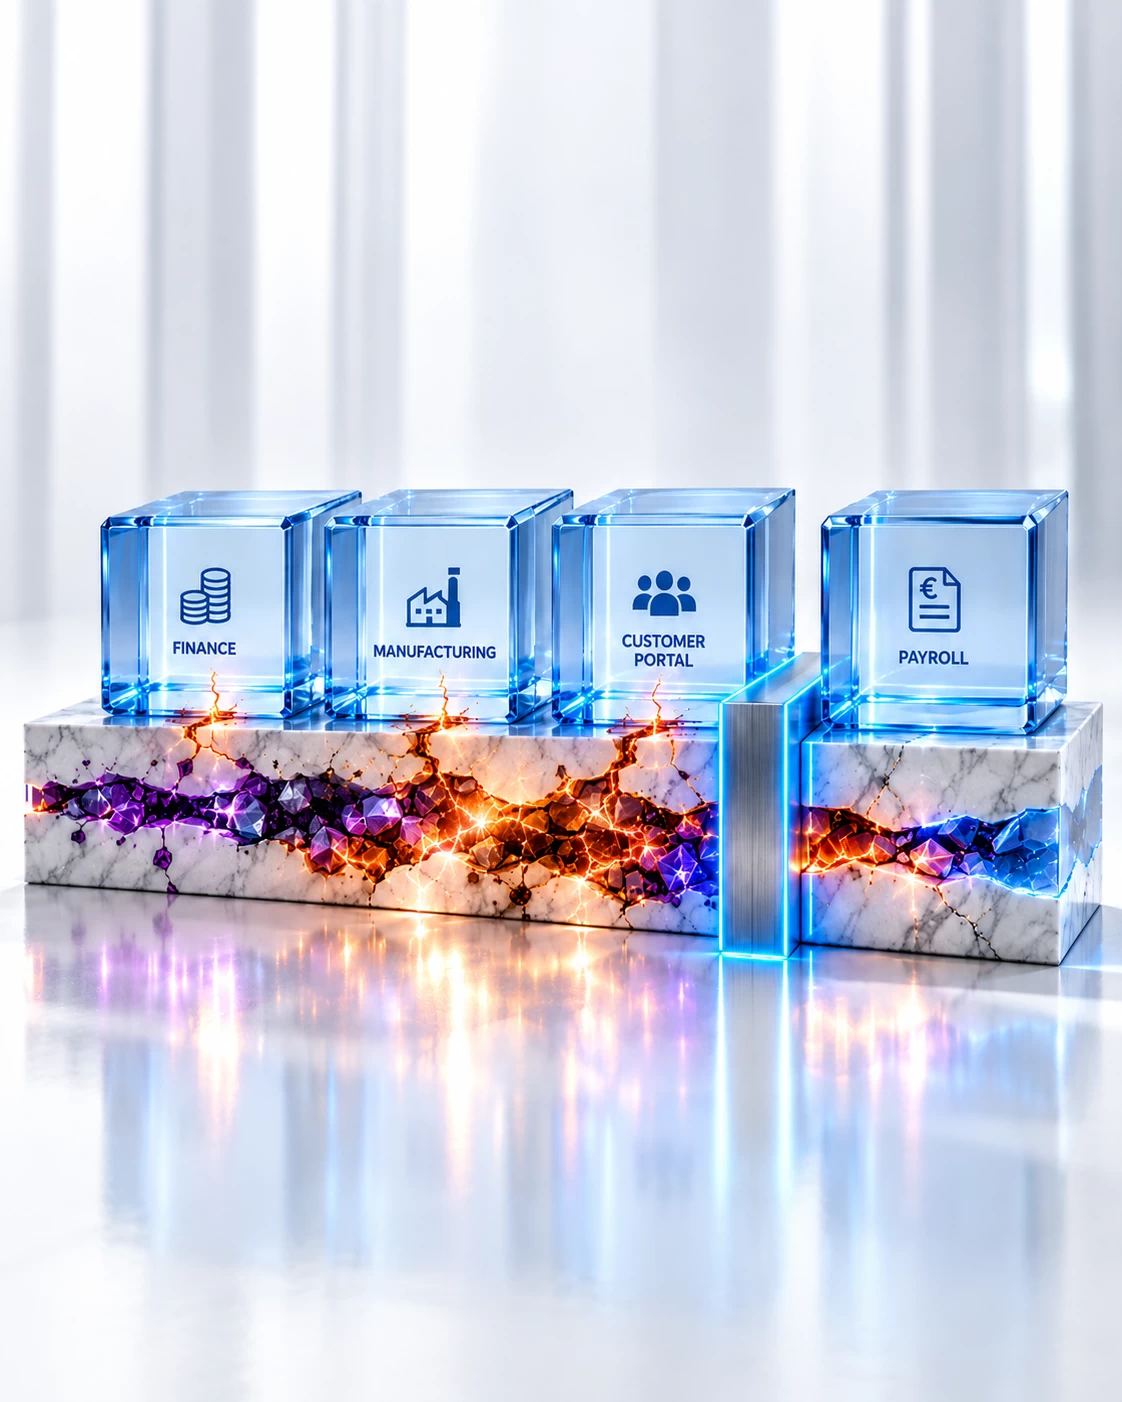
"The Foundation Failed While the Building Still Stood" examines what happens when several apparently separate services rely on a shared host, storage, identity or management layer that becomes unsafe. The impact can cross application boundaries, while recovery teams discover that their own access and tools depend on the affected infrastructure. The ESXiArgs advisory illustrates risk concentrated at the host layer; Clorox’s filing describes wider business consequences from infrastructure disruption without establishing a hypervisor cause. Your executive team needs to understand those dependencies and the practical options for isolation, reduced operation and recovery.
The next publication, "When Patient Data Becomes Long-Term Leverage", turns to a consequence that can survive infrastructure restoration: sensitive information outside your organisation’s custody and the continuing pressure it can create for patients and the institution.
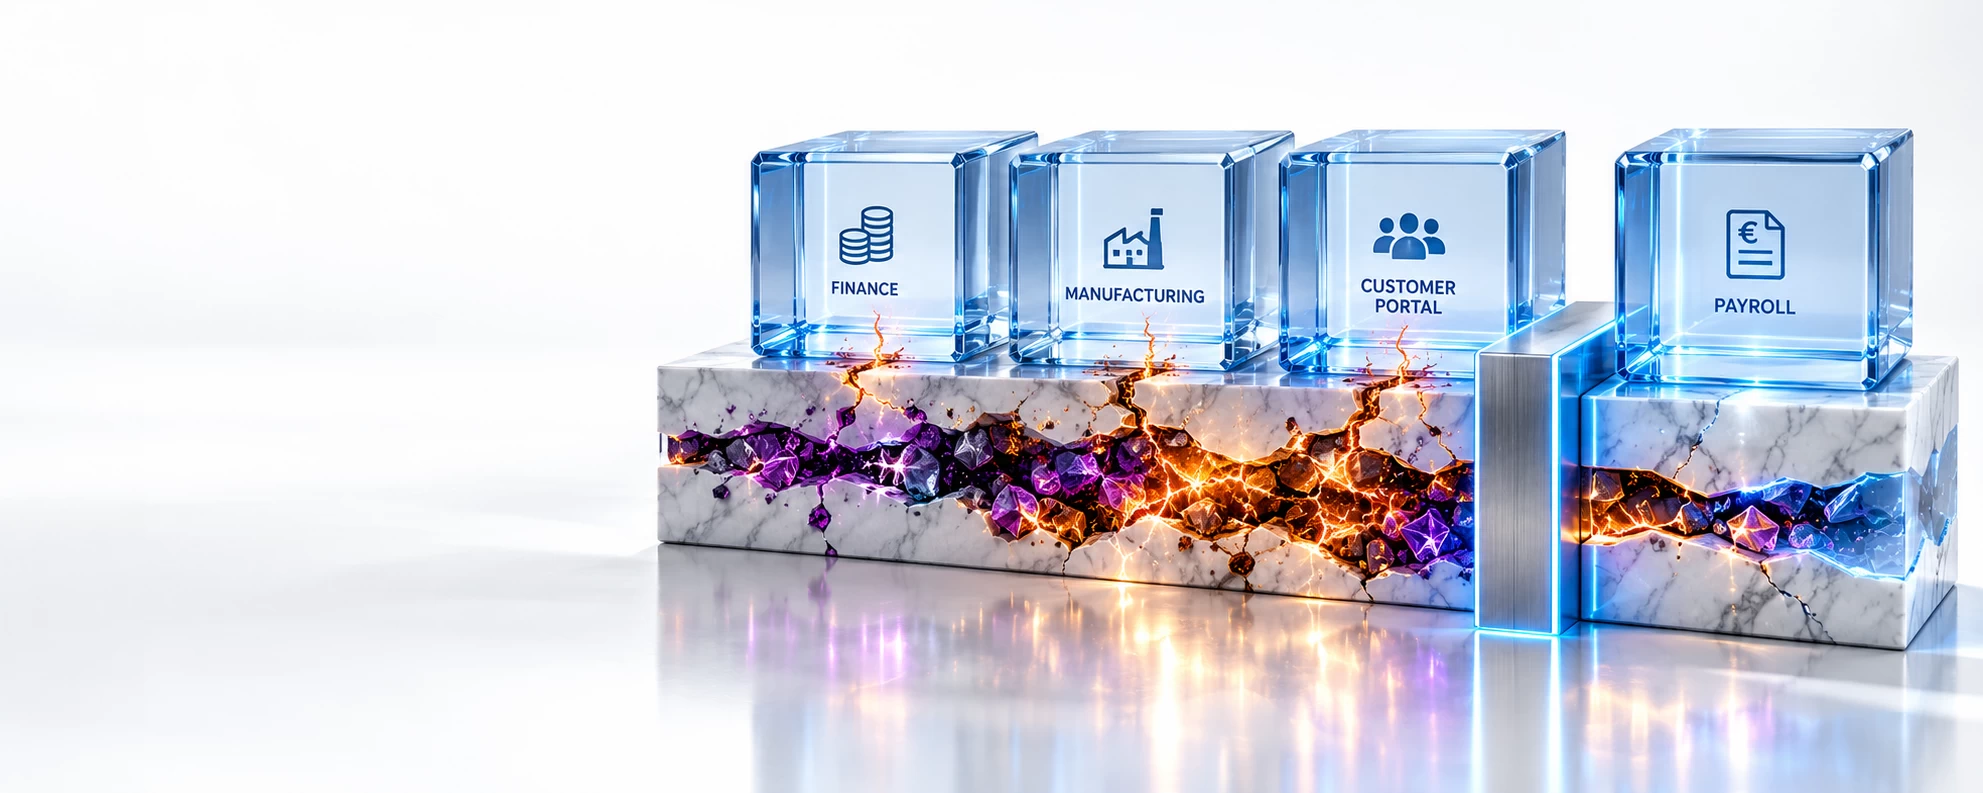
On your organisation’s business map, the services may look separate. Finance has its own systems, manufacturing has its own planning tools and the customer portal has its own application. Payroll, reporting, warehousing, identity and order processing appear as different boxes, owned by different teams and discussed in different meetings. Yet the weakness may sit in the shared layer beneath those applications, laptops and databases.
From outside, your organisation can still look like a building that is standing. The brand remains visible, people are working and some systems still respond. The public does not immediately see the architecture beneath the surface. Inside, floors that looked separate on the drawing may depend on the same damaged structure.
A cyber incident changes shape when that shared foundation becomes part of the crisis. Your organisation may still appear to stand while the services that make it operate begin to fail together.
Diagrams help your executive team understand the organisation: finance here, operations there and customer service somewhere else. The architecture appears divisible, suggesting that if one service fails, another should remain available. That separation holds only when it is operationally real.
Apparently separate services may rely on the same virtualisation cluster, storage layer, identity platform, management plane or administrative path. Those shared foundations help modern enterprises scale by concentrating resources and simplifying administration. The risk appears when that concentration is mistaken for containment.
A boundary on your business map becomes useful during an incident only if your teams can still isolate, govern and recover the services on either side of it.
As early as 2023, the joint CISA/FBI advisory on the ESXiArgs campaign reported that malicious actors may have exploited known vulnerabilities in unpatched, out-of-service or outdated VMware ESXi servers. The ransomware encrypted configuration files on ESXi hosts and could render the virtual machines on them unusable. CISA and the FBI advised affected organisations to quarantine or take compromised hosts offline before attempting recovery. The case supports a narrow point: one shared host layer can place multiple workloads at risk at the same time.
Cyber Security Advisory - ESXiArgs Ransomware Virtual Machine Recovery Guidance
https://www.ic3.gov/CSA/2023/230208.pdf
In October 2026, the consequences of shared infrastructure disruption were visible across customers of IDCF Cloud. IDC Frontier’s 8 October update confirmed a ransomware attack affecting 495 companies and local governments. Virtual servers in four zones of East Japan Region 1 had stopped and could not be restarted.
The operator’s 14 October update confirmed that backup data could be retrieved for 194 affected customers using its snapshot feature, with restoration options being assessed individually. Those notices establish a disruption spanning many customers and a recovery process dependent on the available copies. They do not identify a particular vCenter exploit as the entry point.
ASCII - Ransomware attack affects 495 organisations 9 October 2026
This edition covers the IDC Frontier’s 8 October update, including the four affected zones and recovery difficulties.
https://ascii.jp/en/elem/000/004/441/4441355
ASCII - Backup data retrievable for 194 customers
https://ascii.jp/en/elem/000/004/442/4442704/
At the business layer, the consequences were already evident in 2023, when Clorox reported that an August cyberattack had damaged parts of its IT infrastructure. The company took systems offline and used manual ordering and processing at reduced capacity. Order delays and product outages affected net sales and earnings. The filing shows how infrastructure disruption can reach customers and financial performance without identifying a hypervisor as the cause.
United States Securities and Exchange Commission - The Clorox Company
https://www.sec.gov/Archives/edgar/data/21076/000002107623000048/clx-20230930.htm
A comparable operating problem arose at the University of Mississippi Medical Center in February 2026. UMMC reported that ransomware had left its electronic health record and telephone systems unavailable. It took systems down for safety testing, used paper documentation and patient orders for inpatient care, and cancelled statewide clinic operations and elective procedures on 19 and 20 February.
Hospitals and emergency departments remained open during the response. UMMC reported on 2 March that its clinics had resumed normal operations following the disruption. The organisation continued providing essential care, but the loss of shared digital services changed how that care could be delivered. Its statements do not establish a hypervisor failure as the cause.
UMMC - official incident account 20 February 2026
https://www.umc.edu/news/VCNotes/2026/02/20.html
UMMC - care continuity and clinic recovery account 2 March 2026
https://umc.edu/news/News_Articles/2026/03/Cyberattack.html
The 2023 records establish an earlier warning; the 2026 cases show why the dependency question remains current. For your organisation, the test is which shared layers can affect several services and whether those services can be isolated and recovered without relying on the same affected foundation.
The customer does not experience a management plane, and the warehouse does not experience a hypervisor; instead, they experience delays, manual work, unavailable products, and services that cannot be restored with a simple restart.
That translation matters in the incident room. Your technical team may describe the affected layer accurately while the executive team still underestimates the operational consequence. The useful question is which business promises relied on that component remaining trustworthy.
Your teams discover the real dependency map when ordering, production, payments, reporting and recovery converge on infrastructure that has been isolated, damaged or placed under suspicion.
Those dependencies bring the incident into customer commitments, operating decisions and the choices your executive team can still make.
Foundation incidents create a second problem after disruption: recovery blindness. In an ordinary failure, the tools used to see, diagnose and restore the environment usually remain available. Monitoring, identity and management consoles allow recovery teams to compare healthy and unhealthy states.
When the foundation is part of the incident, some of those tools may depend on the same layer now under investigation. Monitoring may run on affected infrastructure. Backup orchestration may rely on the virtual environment. Authentication may depend on shared identity. Recovery documentation may sit behind systems that cannot yet be trusted.
Your incident team is trying to repair the building while locating the keys, drawings, cameras and emergency exits through building systems that may themselves be unsafe.
Recovery becomes slower when the path to understanding the damage has also been impaired. Your executive team must then approve isolation, restoration and reconnection decisions with less reliable visibility.
Infrastructure determines what other controls can still do under pressure. Endpoint protection may remain valuable, but a protected workload still depends on its host. Backups remain essential, but restoration may depend on trusted identity, management access and storage integrity. Detection may produce an alert, but response still requires authority to isolate the right layer without creating uncontrolled business harm.
Resilience depends on whether those control relationships remain usable when a supporting layer becomes unsafe.
Your executive team needs a reliable answer to the architectural questions that shape the decision: which shared layers support the greatest number of critical services, which administrative paths can reach them, what can continue if one must be isolated, and whether the tools needed for recovery depend on the same foundation they are supposed to restore.
Once shared infrastructure becomes the incident, those answers help your executive team judge how much of the building must be treated as unsafe until the evidence supports a different decision.
Containment needs to account for the dependencies concentrated in shared infrastructure. A single layer cannot protect every dependency. Your organisation needs a practical way to retain control before shared infrastructure becomes a risk multiplier.
If an attacker can move towards the systems that concentrate dependency, the incident changes category. More services become suspect. More recovery paths require validation. Isolation becomes politically harder because the technical boundary now cuts across business commitments.
An operational containment layer helps interrupt unsafe movement, malicious behaviour, data exposure and encryption while your executive team is still determining the full shape of the incident. That can preserve boundaries before concentration turns one compromise into a shared consequence. The value lies in being able to act before damage reaches the load-bearing systems and widens the incident.
The building can still look as though it is standing while its foundation has become unsafe. People may still enter and some services may still respond. A dashboard may show partial health while the management layer is suspect and the recovery path is less certain than the architecture diagram suggested. Infrastructure can therefore become part of the incident while your organisation still appears to operate.
Your organisation remains more governable when your teams understand where that foundation sits, how it concentrates business consequence and how to contain harmful activity before it reaches more shared systems.
"When Patient Data Becomes Long-Term Leverage" moves beyond the damaged foundation to information that cannot be brought back under exclusive custody by restoring systems. It asks how exposed patient data can sustain pressure after the technical incident, and why recovery and the end of that leverage are separate outcomes.