Article #24
Published: 26 October 2026
By Stan van Gemert | S10 Group
By Stan van Gemert
Why resilience changed series
The previous publication, "The Service Elevator Became the Attack Path", showed how hostile behaviour can travel through a remote-support route that remains familiar, approved and operational. The tool may be legitimate even when the session and actions moving through it are not.
"When Visibility Does Not Turn Into Action" follows the warning generated by that behaviour. A signal can appear across security, operations, supplier management and risk reporting while the incident continues because nobody owns the next decision, the threshold remains undefined or the available response appears too disruptive.
The next publication, "Detection Does Not Automatically Create Control", takes the problem into the CISO's operating reality. It asks whether a mature security environment can turn a credible alert into proportionate interruption before uncertainty becomes wider operational damage.
At 08:41, imagine a high-confidence signal appearing in several places at once. The security team sees unusual use of a trusted account, operations sees activity touching a critical application, the supplier team recognises the external connection involved and the risk register already describes the dependency.
Security asks whether the route can be restricted. Operations wants more certainty about the service impact. The application owner suggests the next maintenance window, while the supplier manager says the contract owner must approve a change. By lunchtime, the signal is marked under review.
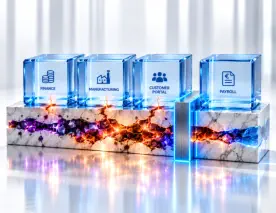
Nothing is hidden. Everyone can see part of the problem, yet no one has a complete path from observation to action.
The failure is not visibility. The signal has not reached a named owner, crossed an agreed decision threshold and produced a move that can change the incident path.
Modern environments produce identity events, endpoint signals, network observations, supplier alerts, cloud logs and operational dashboards. That visibility matters because it can reveal when a trusted route has changed character before the consequence becomes obvious.
A signal can still be accurate, timely and visible to several teams while the underlying behaviour continues. Observation must cross an organisational boundary before it changes the outcome: someone must own the decision, understand the operational consequence and have authority to act before the investigation is complete.
Governance reporting can conceal that boundary. A dashboard may show that a risk is known, a ticket may show that it was assigned and a committee may show that it was discussed. None of those records establishes that harmful activity can be interrupted now.
Signals usually stall for practical rather than dramatic reasons. Five are especially common:
The result is another ticket, another call and another request for information. Additional review may be reasonable, but it should not become the default response because no narrower control move has been made executable.
GitGuardian described finding the public repository, sending nine emails to the commit author and escalating through CERT/CC and direct contacts before reaching CISA. CISA credited the external notification and described taking the affected development environment offline and resetting associated credentials.
NIST Cybersecurity Framework 2.0 separates the functions involved. Detect covers finding and analysing possible compromise. Respond covers action taken regarding a detected incident. Govern establishes roles, responsibilities and authorities. The functions connect, but they do not substitute for one another.
Sources:
GitGuardian - How We Got a CISA GitHub Leak Taken Down in Under a Day
https://blog.gitguardian.com/how-we-got-a-cisa-github-leak-taken-down-in-26-hours/
CISA - Lessons from CISA's Cyber Incident
https://www.cisa.gov/news-events/news/lessons-cisas-cyber-incident
NIST - Cybersecurity Framework 2.0
https://nvlpubs.nist.gov/nistpubs/CSWP/NIST.CSWP.29.pdf
Note: The sources do not prove malicious use, provide a complete internal CISA timeline or establish that CISA ignored its own SOC alerts. The example supports only the need to connect reporting, ownership and response.
One reason teams hesitate is that action is imagined as a binary choice: leave the environment untouched or stop the whole service. Effective control is usually more selective.
Depending on the architecture and operational consequence, a bounded move might suspend one supplier connection, revoke one class of privileged session, isolate one segment, narrow one data flow, pause a remote-management route or throttle a suspect interaction while essential activity continues elsewhere.
The right move is not automatically the fastest or most aggressive one. It is the narrowest proportionate intervention that reduces harmful freedom, preserves what must continue and can be observed and reversed under defined conditions.
Known exposure is often recorded as accepted risk, and that can be a legitimate decision. Some dependencies cannot be removed immediately, some controls would create greater operational harm and some changes require time.
Acceptance becomes dangerous when it turns into a parking place. A live acceptance should still name the owner, reason, review or expiry point, compensating controls, the trigger that changes the decision and the bounded move available if the condition deteriorates.
Not every risk needs executive attention. The decision does need to remain traceable and responsive to changing facts. The important question is whether new information can cause your organisation to do something different.
A practical controllability test follows one high-consequence signal through six connected questions:
If the chain breaks, the missing link is the real improvement priority. More telemetry cannot resolve an absent owner. A named owner cannot help when every useful action depends on an approval route that fails under pressure. A technical move is not controllable when nobody understands its operational consequence.
Who can turn this signal into a proportionate control move?
In healthcare, an anomaly may require a narrow restriction without obscuring information needed for care. In finance, a trusted connection may need to be limited while essential transactions continue under tighter control. In manufacturing, a remote-support route may need to be separated from plant operations without creating a new safety risk.
The signal, acceptable disruption and technical response will differ. The common requirement is a complete path from credible warning to ownership, proportionate action and confirmation that the action worked.
Our platform supplies the technical interruption that visibility alone cannot deliver. When prevention has been bypassed, it detects and stops supported malicious behaviour before one compromised identity, server path, data route or virtual workload can carry the security breach further.
Ransomware Containment automatically isolates the responsible user or session when active encryption is detected across supported SMB and NFS file activity. Optional Server Intrusion Protection stops hostile server access involving compromised administrator credentials, interrupting reconnaissance, lateral movement, data theft and attempts to reach or destroy backups. Optional Virtual Server Protection protects supported VMware and Hyper-V environments when malicious activity targets the shared virtual foundation.
These capabilities operate on one containment platform according to the features deployed and configured. Their technical action does not depend on the executive team first completing the wider operational analysis. Our platform stops progression that would otherwise continue while your teams investigate the cause and manage continuity, communication, reporting and recovery.
Curious how our platform detects and stops ransomware encryption, hostile server access, reconnaissance, lateral movement, data theft and attacks against virtual infrastructure? Schedule a conversation with us.
We will present how Ransomware Containment and its optional Server Intrusion Protection and Virtual Server Protection features operate during a live security breach. Where a practical demonstration adds value afterwards, we can arrange a controlled Ransomware Containment assessment comparing active-encryption outcomes while your existing security controls remain active throughout.
A visible signal is often your first useful advantage. That advantage disappears when the warning enters a queue with no owner, no threshold and no move capable of changing the incident.
More visibility can improve judgement, but it cannot supply accountability or define the wider operational consequence. Those responsibilities must already have owners. Technical containment must also be present so active malicious behaviour is stopped rather than merely observed.
The practical measure of visibility is therefore not how much your organisation can display. It is whether a credible signal changes what the security breach can reach next.
"Detection Does Not Automatically Create Control" takes the visibility-to-action gap into the CISO's operating reality. It examines why accurate alerts, capable teams and mature security tools can still leave the decisive containment move unresolved when trusted routes and essential operations are involved.
This next article asks whether your organisation has more than awareness: a proportionate technical interruption and the authority to manage the operational consequences that follow.
Wednesday 28 Oct 2026, Leadership-series #8: "Detection Does Not Automatically Create Control"
Friday 30 Oct 2026, Operational Attack-series #8: "When the System That Defines Trust Can No Longer Be Trusted"
Monday 2 Nov 2026, Resilience-series #9: "When Every Minute Matters, Readiness Cannot Wait"